Claim Your FREE Website Audit—Limited Time Offer | Contact Us NOW!

Author name: Sikdar Technologies

ERP customization vs integration in 2026 for legacy system modernization
Business & Digital Strategy, Industry Solutions, Odoo ERP & Business Systems, System Architecture & APIs

Enterprise ERP Customization vs Integration in 2026: The Decision Framework for Legacy System Modernization

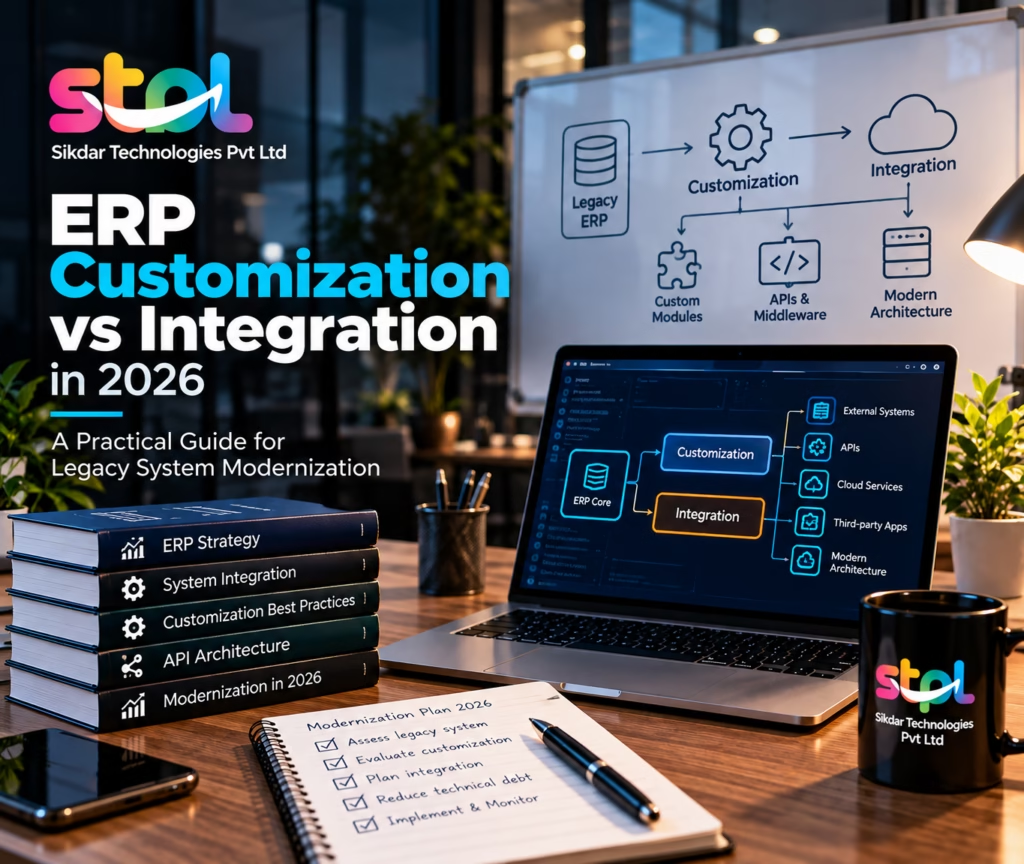
ENTERPRISE TECHNOLOGY • 2026 STRATEGIC REPORT Enterprise ERP Customization vs Integration in 2026 Discover the definitive 2026 decision framework for legacy system modernization. Learn how CTOs balance custom code, API integration, and enterprise technical debt. Updated: September 30, 2026 14 min read Enterprise Architecture Frontend / Clients Web & Mobile Apps → Secure Gateway API Management → Core Engine ERP Core & Middleware Table of Contents Introduction Executive Summary 1. What Is ERP Customization? 2. What Is ERP Integration? 3. Comparison Matrix 4. The 2026 Decision Framework 5. Evaluation Matrix Table 6. Over-Customization & Technical Debt 7. API-First & Composable ERP 8. Modernization Architecture 9. Odoo ERP Context 10. Total Cost of Ownership (TCO) 11. Security Considerations 12. Modernization Roadmap 13. Common Pitfalls 14. Frequently Asked Questions Sources & References Introduction Enterprise resource planning systems form the digital backbone of many organizations. However, technology leaders often face difficult architecture choices when they modernize legacy systems. In particular, evaluating ERP customization vs integration helps determine which functions should stay in the core and which should run on external platforms. Historically, firms relied heavily on custom code inside private database layers. Although this approach allowed teams to tailor workflows quickly, it also made upgrades harder and increased maintenance work. As a result, poorly governed integration can create fragmented data models and complex middleware bottlenecks. This guide gives IT directors and enterprise architects a practical framework for evaluating ERP customization vs integration in 2026. More importantly, it shows how to balance faster delivery with long-term architectural flexibility. ERP modernization architecture: customization, integration, and enterprise core boundaries. Executive Summary: The 2026 Architecture Playbook Modernizing legacy environments requires a practical approach rather than a fixed rule. In practice, neither core code changes nor standalone integration solves every business need. The Core Problem Monolithic legacy software can struggle to support fast digital initiatives without major code changes. Moreover, Over time, those changes can lock enterprises into costly upgrade cycles. The Architectural Choice In practice, the goal is to balance core changes with decoupled services. At the same time, API-first strategies and modular frameworks can isolate changes more safely. Customization Makes Sense When: In addition, the process is central to a proprietary competitive advantage and requires strict transaction consistency. Integration Makes Sense When: Best-of-breed cloud SaaS tools exist, or multi-system data sharing across separate business units remains mandatory. Hybrid Architecture Makes Sense When: Core financial ledgers remain secure inside the database while specialized customer portals operate externally. 1. What Is ERP Customization? ERP Customization vs Integration Explained In practice, ERP customization means changing source code, database structures, or business rules to support workflows that standard features do not cover. Featured Definition: What is ERP customization? Meanwhile, ERP customization changes native software code or database schemas to support unique operating procedures. In addition, Unlike standard configuration, it adds custom code that changes how the core system behaves. Key Dimensions of Customization For example, Core Business Logic: Modifying core calculation engines, ledger posting rules, or inventory algorithms. In addition, Workflow Customization: Therefore, Altering multi-level approval flows and automated notification triggers. Similarly, Database-Level Changes: In practice, Adding custom tables, modifying database relationships, or writing custom stored procedures. Moreover, UI Customization: Meanwhile, Injecting custom scripts, modifying screen layouts, or adding custom field checks. The Customization Paradox: Custom modifications deliver immediate satisfaction by matching habits, but they fundamentally disrupt upgrade paths, turning routine patches into complex refactoring tasks. 2. What Is ERP Integration? ERP Customization vs Integration Explained Furthermore, ERP integration connects enterprise software with external applications such as CRM engines, data warehouses, and microservices. For example, In this way, teams can synchronize data without changing the core. Featured Definition: What is ERP integration? Consequently, ERP integration uses APIs, middleware, and event buses to connect different enterprise systems. Therefore, teams can extend capabilities while keeping the core stable. Modern Integration Mechanisms Meanwhile, REST APIs & GraphQL: Furthermore, Lightweight endpoints facilitating synchronous data exchange and precise data queries. As a result, Webhooks & Event-Driven Architecture: Real-time push notifications triggered by specific database events (e.g., order created). Therefore, iPaaS Platforms: In contrast, Cloud middleware providing pre-built connectors, data mapping, and error handling. In practice, Enterprise Service Bus: Similarly, Centralized routing and message routing layers for complex legacy environments. 3. ERP Customization vs Integration: Side-by-Side Comparison In contrast, Evaluating these choices requires a clear view of operational, financial, and technical trade-offs. Therefore, the matrix below compares customization with integration. Evaluation Criteria ERP Customization ERP Integration Implementation Speed Fast at first, but delivery slows as technical debt grows. Requires initial API layers and middleware contracts. Initial Cost Moderate to High (requires specialized core developers). Moderate (requires integration tooling, licenses, and API design). Long-Term Maintenance High; custom code can break during version upgrades. Low to Moderate; managed through decoupled API contracts. Upgrade Complexity High; often requires code merging and regression testing. Lower; core upgrades can happen separately from external apps. Technical Debt Can grow quickly and make the core harder to maintain. Can be reduced through clear boundaries and modular services. Data Consistency Strong transactional consistency within one database. Requires careful handling of retries and eventual consistency. Vendor Dependency Can increase reliance on custom developers and legacy code. Can spread dependencies across standard APIs and SaaS partners. Business Agility Can become rigid and make core process changes harder. Can remain flexible because external systems can change without changing the core. ERP customization vs integration decision framework for enterprise modernization. 4. The 2026 Enterprise ERP Modernization Decision Framework: ERP Customization vs Integration Similarly, To reduce guesswork, enterprise architects can use a clear decision framework. As a result, In turn, this framework classifies each requested feature or modernization requirement. Choose Customization When: In practice, the process is strictly native to the ERP data model (e.g., statutory tax calculations). Furthermore, Deep, atomic database transactions are mandatory to prevent ledger discrepancies. Consequently, The workflow represents core enterprise business IP and business advantage. In contrast, Introducing external middleware would inject high latency into operations. Choose Integration When: At the same time,
google.com, pub-8966458381222183, DIRECT, f08c47fec0942fa0
Junior System Design Interview Guide – Practical System Design Concepts for Software Engineering Interviews | Sikdar Technologies
Sikdar Technologies Academy

Junior System Design Interview Guide for Freshers | Sikdar Technologies

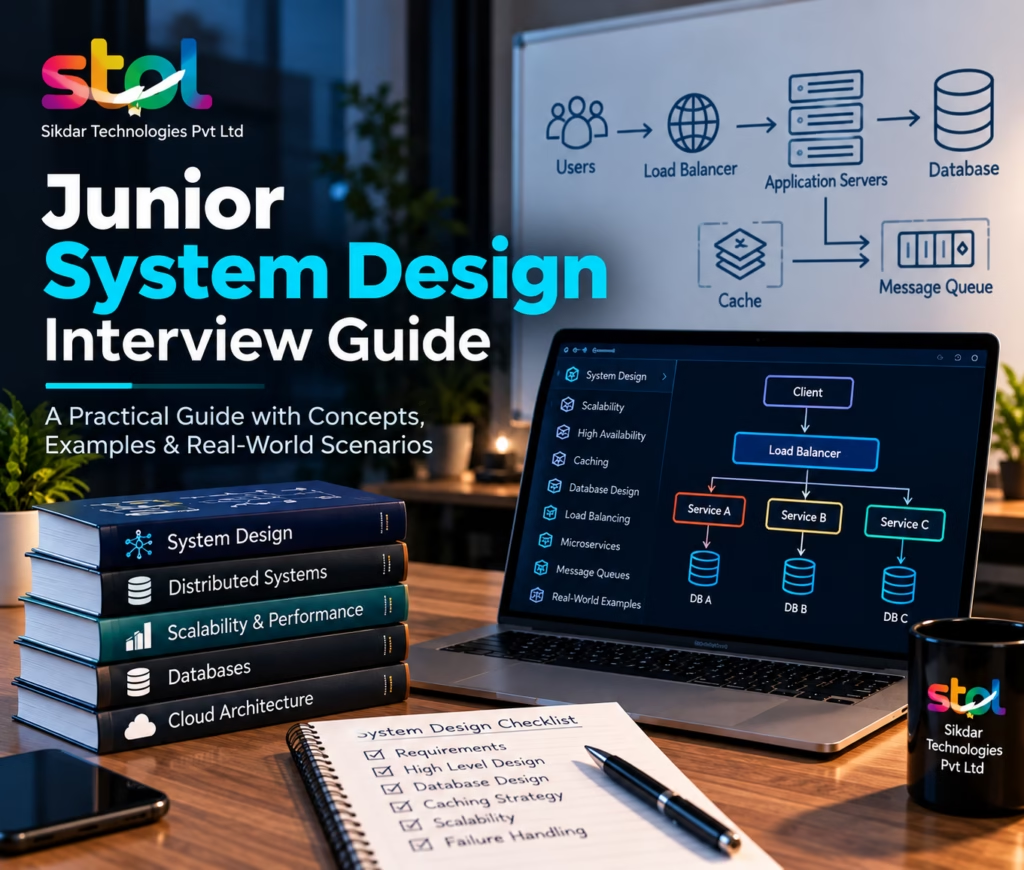
Career Preparation • System Architecture Junior System Design Interview Guide: How Freshers Can Prepare and Design Scalable Systems A practical, beginner-friendly roadmap for understanding requirements, APIs, databases, scalability, caching, queues, and architectural trade-offs. Target: Freshers, Final-Year Students, Junior Developers (0–2 YOE) Estimated Read Time: 18 Minutes Curriculum Resource: Sikdar Technologies Academy Table of Contents Show Introduction 1. What Is System Design? 2. Do Juniors Need System Design? 3. What Interviewers Look For 4. The 7-Step Interview Framework 5. Step 1 — Clarify Requirements 6. Step 2 — Functional vs Non-Functional 7. Step 3 — Capacity Estimation 8. Step 4 — Designing Clean APIs 9. Step 5 — Database Selection 10. Step 6 — Scaling Fundamentals 11. Caching Basics 12. CDN Basics 13. Message Queues Explained 14. 8 Common Junior Questions 15. Complete Walkthrough: URL Shortener 16. Beginner Mistakes to Avoid 17. How to Communicate in Interviews 18. 30-Day Preparation Roadmap 19. Printable Interview Checklist 20. Frequently Asked Questions Preparing for a junior system design interview often feels intimidating for students, freshers, and early-career software engineers. In fact, most university computer science curricula teach Data Structures and Algorithms (DSA), object-oriented programming, and relational database management systems. However, few degree programs teach how these moving pieces interact inside a scalable web application handling millions of requests. Consequently, when faced with an open-ended prompt like “Design a URL Shortener” or “Design a Simple Notification System,” beginners frequently panic. Furthermore, many candidates mistakenly believe the interviewer expects them to design enterprise-grade, globally distributed systems running on Kubernetes clusters. In reality, engineering hiring teams look for something simpler: structured logical thinking, systematic requirement clarification, clean API design, database schema fundamentals, and clear communication. Therefore, this comprehensive guide provides a beginner-friendly roadmap. Specifically, it walks you through core architectural concepts without confusing industry jargon, helping you approach your first junior system design interview with structure, confidence, and clarity. 1. What Is System Design in a Junior System Design Interview? System design is essentially the process of defining the architecture, components, modules, interfaces, and data for a software system to satisfy specified operational requirements. For example, think of system design as creating an architectural blueprint for a building before laying bricks. The Three-Tier Foundational Flow At its most fundamental level, every web application starts with a simple three-tier architecture. In addition, each layer holds a specific operational responsibility: Foundational Web Request Flow 1. Client Tier (Browser / Mobile App) Initiates an HTTP/HTTPS network request across the internet ↓ 2. Application Server Tier (Node.js, Spring Boot, Django, Go) Executes business logic, authenticates users, validates input schemas ↓ 3. Database Tier (PostgreSQL, MySQL, MongoDB) Persists application state, queries records, maintains ACID transactions Scaling the Basic Layers As user traffic grows from 10 users to 100,000 users, single application servers and single database instances encounter CPU, memory, and disk I/O bottlenecks. Therefore, system design becomes the disciplined practice of introducing components—such as Load Balancers, Caches, Content Delivery Networks (CDNs), and Message Queues—to remove these single points of failure and keep the application responsive. 2. Do Junior Developers Really Need System Design? Naturally, hiring practices vary across technology companies. While some early-stage startups and legacy enterprises focus exclusively on coding problems and DSA, many modern software companies, mid-sized product firms, and tech leaders include an introductory system design or object-oriented design round for junior software engineers (0–2 years of experience). Junior vs. Senior Expectations First and foremost, interviewers do not expect a junior candidate to design high-throughput multi-region active-active clusters or write Paxos consensus algorithms. Instead, interviewers want to verify that you understand how real-world software functions beyond a local terminal window. Core Expectations for Entry-Level Roles Thus, here is a realistic summary of junior interview expectations: What Junior Candidates Should Know: For example, you should understand how a client talks to a server, how to structure clean RESTful endpoints, when to pick a relational database over a document store, why database indexing speeds up queries, and how caching relieves database read pressure. What Juniors Do NOT Need to Master: In contrast, you do not need to master advanced multi-datacenter consensus protocols, intricate database engine internals, complex event sourcing frameworks, or distributed transactions across heterogeneous microservices. 3. What Interviewers Look For in a Junior System Design Interview During a 45-minute junior interview, evaluators track specific core competencies. Specifically, the following evaluation matrix highlights what interviewers examine: Junior Architectural Matrix Consequently, candidates can review the key areas that hiring teams inspect during evaluation: Core Competency What the Interviewer Evaluates Expected Junior Proficiency Requirement Clarification Does the candidate ask thoughtful questions or make blind assumptions? Identifies core features, target users, and key operational constraints before drawing boxes. API Design Can the candidate structure clean, intuitive HTTP endpoints? Chooses appropriate HTTP verbs, paths, request bodies, and standard status codes. Database Selection Can the candidate justify relational versus non-relational storage? Understands schema consistency, foreign key relationships, and ACID guarantees vs. flexible document models. Scalability Basics Does the candidate understand how systems handle growing traffic? Explains vertical scaling limits and how to add multiple stateless servers behind a load balancer. Caching Fundamentals Does the candidate recognize when to store hot data in memory? Explains cache hits, cache misses, Time-To-Live (TTL), and basic cache invalidation challenges. Trade-off Awareness Does the candidate recognize that every architectural choice has a cost? Explains simple trade-offs: e.g., speed vs. memory cost, or consistency vs. immediate availability. Technical Communication Can the candidate explain ideas collaboratively? Communicates thoughts aloud, takes hints positively, and articulates technical decisions cleanly. 4. The 7-Step System Design Interview Framework Walking into an interview without a structured plan leads to wandering discussions and incomplete architectures. In contrast, candidates who succeed follow a clear, repeatable framework. The Complete Step-by-Step Flow Therefore, memorize these seven progressive milestones to keep your interview organized: Initial Requirement Clarification: Ask targeted questions to define scope and operational boundaries. Requirement Categorization: Separate functional user features from non-functional performance goals. Quantitative Scale Estimation: Perform back-of-the-envelope calculations to identify system load. Interface and API Contracts: Define endpoints,

google.com, pub-8966458381222183, DIRECT, f08c47fec0942fa0
LLM Token Cost Optimization: Enterprise Latency and Cost Guide – Sikdar Technologies
AI & Automation, Business & Digital Strategy

LLM Token Cost Optimization: Enterprise Latency & Cost Guide

AI Engineering & LLM Architecture LLM Token Cost & Latency Optimization: A Production Engineering Guide Learn how production engineering teams reduce LLM API costs, improve Time-to-First-Token (TTFT), improve RAG pipelines, and scale AI applications with predictable performance. Architectural Technical Guide Estimated Read Time: 16 Minutes Sikdar Technologies · AI Engineering Contents Show Menu 1. LLM Token Economics 2. Cost vs. Latency Dynamics 3. Unnecessary Token Drivers 4. Systematic Prompt Optimization 5. Model Selection & Routing 6. Exact & Semantic Caching 7. Latency Engineering (TTFT/TTLT) 8. Production RAG Optimization 9. Controlling Agentic Explosion 10. Production Observability 11. Reference System Architecture Interactive Cost Calculator 12. Optimization Checklist 13. Common Antipatterns 14. Phased Enterprise Roadmap Frequently Asked Questions Executing an effective LLM token cost optimization strategy has moved from an early cost concern to a core software engineering task. For example, when engineering teams deploy large language model applications into production environments, their early proof-of-concept budgets can rise quickly under production traffic. As a result, workflows that cost pennies during local evaluations quickly generate thousands of dollars in monthly API consumption when exposed to steady enterprise traffic. At the same time, end-to-end response times can degrade. For example, client applications can stall while they wait for sequential tool executions. In addition, chat completions may re-process too much context, while multi-turn agents can enter recursive reasoning loops that consume extra compute. Solving these challenges requires a clear systems approach. LLM latency optimization and inference cost reduction are related but distinct engineering challenges. Achieving predictable efficiency across enterprise LLM pipelines requires inspecting token mechanics, designing efficient prompt structures, implementing semantic caching layers, and deploying automatic model routing. 1. Understanding LLM Token Economics First, every generative AI application interacts with foundation models through tokens—small text units that represent characters, subwords, or byte pairs. In practice, model providers price inference differently based on how input and output tokens are processed: input tokens (prompting, context, system instructions, schemas) are processed in parallel, whereas output tokens (generation, function call arguments, final synthesis) require sequential autoregressive forward passes across GPU clusters. In practice, output tokens are often priced higher than input tokens, although the exact ratio varies by provider, model, and pricing tier. For example, consider standard provider pricing structures across the AI ecosystem: Token Category Processing Type Relative Unit Cost Engineering Optimization Objective Input Tokens (Standard) Parallel Pre-fill Base tier ($X / 1M) Prune conversational history, compact schemas, compress context. Input Tokens (Cached) KV-Cache Pointer Read 10% to 50% of Base Maintain static system prefix order to trigger provider-level prompt caching. Output Tokens Autoregressive Generation 300% to 500% of Base Enforce structured output length, stop sequences, and concise response schemas. Tool / Function Schemas Repeated Input Injection Base tier per invocation Prune unused parameter descriptions; expose tools conditionally. A Simple Token Cost Example Illustrative Production Token Math Suppose an enterprise assistant handles 100,000 requests per day. Each query includes an unoptimized 4,000-token system context (input) and yields a 500-token verbose explanation (output). Assuming illustrative rates of $2.50 per 1M input tokens and $10.00 per 1M output tokens: • Daily Input: 400M tokens × $2.50 = $1,000/day • Daily Output: 50M tokens × $10.00 = $500/day • Total Inference Spend: $1,500/day ($45,000/month) Therefore, for this illustrative scenario, reducing the prompt to 1,200 input tokens and the response to 150 output tokens would materially lower estimated spend. However, actual savings depend on the model, provider pricing, cache eligibility, and workload quality. 2. The Relationship Between Tokens, Cost, and Latency In practice, engineers often assume that token reduction translates linearly into latency reduction. However, this assumption is incomplete. Instead, LLM inference separates into two main compute phases: The Pre-fill Phase (Time to First Token – TTFT): The model ingests all input tokens concurrently. Modern matrix multiplication kernels (such as FlashAttention) process this phase rapidly across high-bandwidth tensor cores. While a larger prompt increases TTFT, it does so sub-linearly until memory bus or context boundaries are saturated. The Autoregressive Generation Phase (Time to Last Token – TTLT): The model emits tokens one by one. Every generated token requires an entire memory load of all model weights across the accelerator’s HBM (High Bandwidth Memory). Thus, output token count directly governs user-perceived stream duration and request throughput. The diagram below models this latency breakdown across network transport, context pre-fill, autoregressive decoding, and serialization: LLM Request Latency Decomposition 1. Network Roundtrip & Ingress (50 – 150ms) TLS handshake, API gateway authentication, JSON payload parsing ↓ 2. Context Pre-fill Phase → Determines TTFT Ingests System Prompt + RAG Context + History in parallel via tensor compute ↓ 3. Autoregressive Generation Loop → Determines TTLT Sequential forward passes: Token 1 → Token 2 → Token N (Memory-bandwidth bound) ↓ 4. Client Stream Finalization & Egress Client buffer flush, telemetry instrumentation, connection teardown As a result, spending development time reducing 100 input tokens yields negligible latency improvement compared to cutting 100 output tokens. On the other hand, reducing input tokens can produce the largest immediate financial savings in high-volume pipelines. 3. The Biggest Sources of Unnecessary Token Usage In practice, uncontrolled token inflation often comes from unpruned context, poorly designed schemas, and uncontrolled retrieval loops. For example, engineering audits conducted on production systems routinely find the following root causes: System Component Why It Increases Cost & Latency Production Optimization Pattern Oversized System Prompts Developers bundle edge-case formatting rules, markdown directives, and excessive behavioral guidelines on every call. Modularize system instructions into lightweight target micro-prompts; leverage prefix prompt caching. Unpruned Chat History Append-only arrays continuously re-transmit early conversational pleasantries and outdated turns across multi-turn sessions. Apply sliding-window memory buffers or stateful summaries that discard ephemeral interaction turns. Unfiltered Tool Outputs Raw SQL query responses or external REST JSON payloads with 80+ unused metadata keys get dumped directly into the LLM context. Pass API responses through schema projection middleware to strip extra fields prior to LLM injection. Oversized RAG Chunks Retrieving raw 1,500-token document blocks introduces massive non-relevant prose into the attention window. Implement parent-document retrieval with 250-token child chunks

google.com, pub-8966458381222183, DIRECT, f08c47fec0942fa0
Monolithic to Microservices Migration Strategy 2026 Guide – Sikdar Technologies
Cloud & DevOps, Industry Solutions, System Architecture & APIs

Monolithic to Microservices Migration Strategy: 2026 Guide

Home / Solutions / Monolithic to Microservices Migration ENTERPRISE SOFTWARE MODERNIZATION Modernizing Monolithic Applications to Event-Driven Microservices: Migration Framework A definitive systems engineering roadmap for CTOs and enterprise architects executing a disciplined monolithic to microservices migration strategy without operational disruption. Published: September 2026 Read Time: 18 min read Domain: Enterprise Architecture & Distributed Systems Request an Architecture Audit Schedule Technical Consultation API GATEWAY / PROXY Strangler Interception Layer LEGACY MONOLITH Residual Core Logic NEW MICROSERVICES Autonomous Services EVENT BROKER (Kafka / RabbitMQ / AWS EventBridge) Table of Contents 1. The Modernization Imperative 2. Understanding Monoliths 3. Monolith vs. Modular vs. Microservices 4. When to Modernize 5. The Strangler Fig Pattern 6. Domain-Driven Design Boundaries 7. Event-Driven Communication 8. Database Ownership & State 9. Fault Tolerance & Code Example 10. Distributed AI Alignment 11. Step-by-Step Roadmap 12. Migration Risks 13. Real-World Use Cases 14. Frequently Asked Questions 15. Next Steps Architectural Executive Summary Legacy enterprise applications inevitably encounter structural ceilings: tightly coupled release cycles, deployment blast radiuses that endanger mission-critical workflows, and single-point-of-failure databases. However, attempting a “big-bang” rewrite consistently introduces severe delivery risks and business disruption. A disciplined monolithic to microservices migration strategy leverages the Strangler Fig pattern, Domain-Driven Design (DDD), and asynchronous event streaming. This framework enables engineering organizations to incrementally extract bounded contexts into autonomous microservices while keeping legacy revenue engines online throughout the transition. 1. Why Enterprise Application Modernization Matters For mid-market and enterprise organizations, software assets built over the past decade frequently represent both the company’s core revenue engine and its greatest operational liability. Over years of rapid feature additions, boundaries blur. What began as a structured application degrades into an interconnected codebase where a minor change in the billing module introduces critical defects in inventory management. Modernizing legacy applications is not merely an exercise in upgrading technology stacks; it is an organizational imperative to accelerate feature velocity, improve fault isolation, and enable granular scalability. By migrating to event-driven architectures, organizations transition from synchronous, tightly coupled dependencies to distributed, loosely coupled systems capable of continuous deployment. 2. Understanding Monolithic Applications: Characteristics & Validity A monolithic architecture is a software application where all business logic, data access, user interface handling, and integration components reside within a single codebase, deployed as a single executable artifact, and backed by a single shared relational database. Clients / Web / App HTTP Requests Single Monolithic Deployable Unit Auth Module Orders Module Billing Module Shared In-Process Memory & Database Layer Shared Database Single Point of Failure (High Contention) Figure 1: Traditional Monolithic Application Architecture. All functional domains share an execution process and a single relational database. It is crucial to recognize that monoliths are not inherently defective. For early-stage initiatives, small engineering squads, or products with unproven domain boundaries, a well-structured monolith offers unmatched development velocity, zero network serialization latency, simplified end-to-end testing, and trivial deployment pipelines. The failure occurs when a monolith outgrows the organization’s team structure and operational boundaries, causing severe deployment coupling, scaling bottlenecks, and organizational coordination friction. 3. Monolith vs. Modular Monolith vs. Microservices Enterprise architectural decisions must evaluate operational complexity alongside functional requirements. A distributed system introduces significant operational overhead that must be balanced against its scaling benefits. Evaluation Vector Legacy Monolith Modular Monolith Event-Driven Microservices Codebase Boundary Tightly coupled; shared namespaces and models. Strictly bounded internal modules; explicit interfaces. Completely decoupled, independent code repositories. Data Ownership Single shared schema; direct cross-table joins. Logically isolated schemas; cross-domain queries restricted. Strict database-per-service; zero direct database sharing. Deployment Unit Single unified artifact (all or nothing). Single unified artifact or container. Independently deployed containerized services. Communication In-memory function calls. In-memory function calls or in-process event bus. Asynchronous event broker (Kafka/RabbitMQ) & HTTP/gRPC. Failure Blast Radius Global: A single unhandled exception crashes the runtime. Global runtime, but contained domain logic. Isolated: Failure in one service does not crash peers. Operational Overhead Low (simple CI/CD, basic monitoring). Moderate (enforcing boundaries in code reviews). High (service meshes, distributed tracing, Kubernetes). 4. When Should an Enterprise Modernize? Migrating away from a monolith should be driven by concrete business and engineering signals rather than architectural trends. Organizations should evaluate the following criteria: Deployment Bottlenecks: Multiple teams cannot ship features independently; a single failed test halts the deployment pipeline for dozens of engineers. Disproportionate Resource Scaling: A single compute-heavy capability (such as real-time PDF generation or report crunching) requires scaling the entire application instance, driving up cloud infrastructure expenditure. Domain Blast Radius: Memory leaks or CPU spikes in non-critical components bring down mission-critical checkout or authentication flows. Database Contention: High lock contention, complex stored procedures, and monolithic database connection exhaustion impede vertical hardware scaling. Is Your Legacy Application Ready for Modernization? Understand your current architecture, technical constraints, and modernization options before committing to a migration. Explore our custom software development practice. Request an Architecture Audit 5. The Strangler Fig Migration Pattern The industry gold standard for low-risk legacy modernization is the Strangler Fig pattern (originally described by Martin Fowler). Named after tropical vines that seed in the canopy of a host tree and slowly grow downward until replacing the original host, this pattern replaces monolithic functionality incrementally. Clients Traffic API Routing Gateway Path Inspection /api/v1/legacy/* /api/v2/orders/* (New) Legacy Monolithic Application Users • Catalog • (Orders Deprecated) • Invoicing Shrinking Scope Over Time Extracted Orders Microservice Autonomous Service Boundary Dedicated Orders DB Publishes Domain Events Figure 2: The Strangler Fig Migration Pattern. The API Gateway transparently routes extracted paths to new microservices while passing legacy traffic unchanged. The pattern operates through three continuous mechanisms: Transform: Construct a new microservice implementing a targeted business capability using modern cloud-native standards. Coexist: Insert an API gateway or reverse proxy in front of the infrastructure. The gateway intercepts incoming HTTP/REST requests, routing legacy endpoints to the monolith and newly implemented endpoints to the microservice. Eliminate: Once the new service demonstrates production stability and data consistency, deprecate and safely remove the redundant code from the monolithic codebase. 6. Domain-Driven Design & Service Boundaries The most common mistake in microservices migrations is

google.com, pub-8966458381222183, DIRECT, f08c47fec0942fa0
Enterprise Agentic AI Architecture 2026 Guide – Sikdar Technologies
AI & Automation, Business & Digital Strategy, Industry Solutions

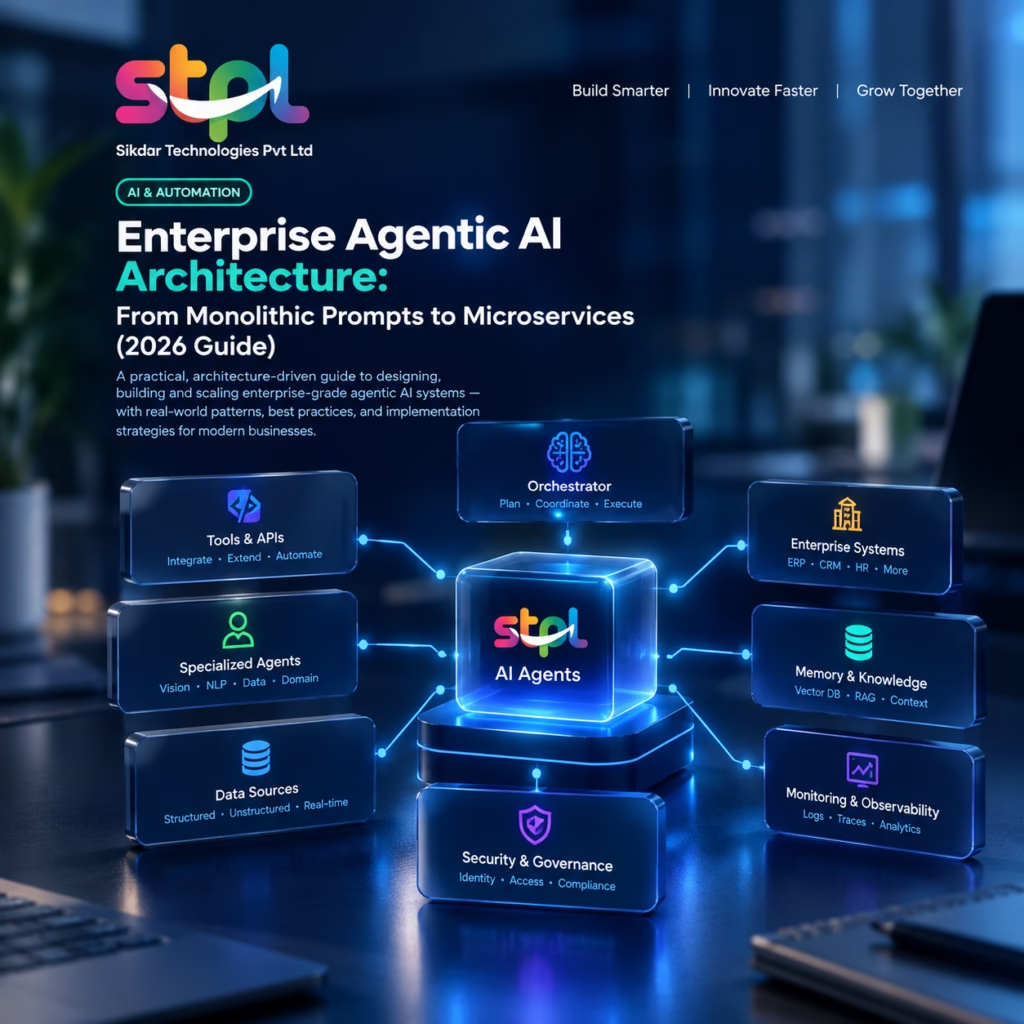
Enterprise Agentic AI Architecture: 2026 Guide | Sikdar Tech

Home / Solutions / AI & ML / Enterprise Agentic AI Architecture AI & AUTOMATION Enterprise Agentic AI Architecture: From Monolithic Prompts to Microservices (2026 Guide) A definitive systems engineering blueprint for CTOs and enterprise architects transitioning from fragile prompt wrappers to distributed, fault-isolated multi-agent microservices. Published: September 22, 2026 Read Time: 16 min read Target Stack: Distributed Cloud & MCP Schedule Technical Consultation Contact Our Team SUPERVISOR NODE DAG Task Planner Worker Agent A Vector Hybrid Search Worker Agent B Enterprise ERP / API Worker Agent C Policy Guardrail EVENT STREAMING BUS (Kafka / SQS / Redis) Table of Contents 1. The Prompt Monolith Crisis 2. What Agentic AI Actually Means 3. Enterprise Reference Architecture 4. Typed Contracts & Code Deep-Dive 5. Microservices vs. Modular Monolith 6. Governance & Human-in-the-Loop 7. 4-Phase Implementation Roadmap 8. Practical Enterprise Use Cases 9. Frequently Asked Questions 10. Architecture Consultation Architectural Executive Summary The enterprise transition to production AI has hit a critical engineering bottleneck: the prompt monolith anti-pattern. Attempting to bundle system instructions, raw vector retrieval, and dozens of external tool interfaces inside a single context window triggers attention dilution, unpredictable token burn, high latency, and complete lack of fault isolation. An enterprise agentic AI architecture treats autonomous agents as single-responsibility microservices. By orchestrating worker agents over event streams, standardizing access through the Model Context Protocol (MCP), and enforcing deterministic schema contracts, organizations achieve resilient, auditable automation capable of scaling to enterprise traffic. 1. The Crisis of the Monolithic Prompt-Based AI System In the initial wave of enterprise AI adoption, applications relied heavily on single-prompt orchestration pipelines. User prompts were concatenated with global persona instructions, unstructured vector search results, and 15 to 30 API schemas, with the combined payload transmitted to a frontier reasoning model. In production systems bound by enterprise Service Level Agreements (SLAs), this design encounters structural breaking points: Attention Dilution and Tool Hallucinations: Overloading model context windows with dozens of tool definitions causes cognitive drift. The model frequently selects incorrect tools or fabricates argument parameters. Zero Fault Isolation: If an integrated ERP lookup or third-party payment service times out within an active reasoning loop, the entire chat session terminates abruptly without state recovery. Exponential Cost & Latency: Passing cumulative conversation history and vector embeddings through expensive models on every turn creates severe token waste and inflates response times beyond 20–30 seconds. User Request (Untyped Input) Monolithic Prompt Context Window (80k+ Tokens) System Instructions, Personas & Business Rules Broad Raw Vector Store Context (RAG) 20+ Exposed Untyped Tool Schemas ⚠️ Anti-Pattern: Cognitive Drift & Zero Fault Isolation Frontier LLM Call Cascading Failure Figure 1: The Monolithic Prompt Anti-Pattern. Combining instructions, retrieval embeddings, and dozens of tool definitions into a single model context window creates high failure rates in production. 2. What Agentic AI Means in Enterprise Applications Unlike conventional chatbots that provide single-turn text completions, an agentic AI system executes goal-directed, autonomous behavior. It decomposes high-level directives into discrete subtasks, invokes internal enterprise tools and APIs, evaluates returned states, and self-corrects when encountering failures. In an enterprise environment, autonomy must be anchored by software engineering rigor: strict schema contracts, deterministic fallbacks, granular access boundaries, and full telemetry logging. Architectural Vector Monolithic Prompt Architecture Agentic Microservices Architecture System Boundary Single prompt context containing global business logic and all tools. Decoupled services adhering to strict Domain-Driven Design (DDD) boundaries. Tool Execution LLM invokes external APIs directly within the active inference loop. Worker agents invoke specialized tool microservices via typed RPC/REST contracts. Protocol Standard Ad-hoc prompt stitching and custom JSON strings. Model Context Protocol (MCP), OpenAPI schemas, and event messaging. Fault Containment A single API failure terminates the entire workflow. Circuit breakers, localized retries, and dead-letter queues preserve state. Cost Optimization Frontier reasoning models are used indiscriminately for every task. Tiered routing: Small models handle classification; frontier models handle planning. 3. Enterprise Agentic AI Reference Architecture To achieve reliable scalability, production architectures isolate concerns across four dedicated planes: API Gateway & Zero-Trust Security Boundary OAuth2 / OIDC Authentication • Ingress Sanitization • Prompt Injection Firewall • Rate Limiting Supervisor Orchestration Engine Goal Deconstruction • DAG Task Scheduling • Dynamic Re-planning Asynchronous Event Bus & State Mesh (Kafka / AWS SQS / Redis Streams) Retrieval Worker Agent Hybrid Search (Dense + Lexical) PostgreSQL (pgvector) / Qdrant Action / ERP Worker Agent Transactional Mutations Odoo ERP / Enterprise APIs Policy & Compliance Agent Deterministic Guardrails AST Parsing / PII Redaction Model Context Protocol (MCP) Standardized Tool Gateway Unified Discovery • Dynamic Schema Binding • OpenTelemetry Tracing Figure 2: Enterprise Agentic AI Microservices Reference Architecture. Decoupling the supervisor orchestrator from specialized workers via an asynchronous event bus ensures high fault tolerance. 1. Ingress & Governance Gateway Acts as the perimeter gate. It validates client identities using OAuth2/OIDC, enforces rate limits, strips malicious prompt-injection payloads, and sanitizes PII before prompts enter inference contexts. 2. Supervisor & Orchestration Plane The supervisor acts as the central planner. It breaks down complex user objectives into a Directed Acyclic Graph (DAG) of actionable tasks. Crucially, the supervisor never runs tools directly—it delegates tasks to worker agents, tracking state and adjusting execution dynamically if a step fails. 3. Specialized Worker Agent Plane Worker agents maintain strict, single-responsibility boundaries. A retrieval agent searches knowledge stores, an action agent executes mutations within systems like Odoo ERP, and a compliance agent evaluates output safety. 4. Model Context Protocol (MCP) & Memory Tier Enterprise systems use the open Model Context Protocol (MCP) to decouple models from underlying databases and microservices. State persistence is divided across three tiers: Working Memory: High-speed key-value caches (Redis) maintaining state across active subtask loops. Semantic Memory: Vector databases (PostgreSQL with pgvector) supporting hybrid retrieval. Episodic Memory: Append-only event logs recording decisions, tool payloads, and operator approvals for regulatory compliance. Architecting Scalable Custom AI Software? Moving from prototypes to enterprise production requires clean architecture. Explore our custom software development services or book an architecture review. Book an Architecture Consultation 4. Engineering Deep-Dive: Typed Tool Contracts & Fault Handling Production stability requires

google.com, pub-8966458381222183, DIRECT, f08c47fec0942fa0
Full Stack developer
Industry Solutions, Sikdar Technologies Academy, Software Development, System Architecture & APIs

Is a Coding Degree Obsolete in 2026? Full Stack Career Guide

Home / Academy / Full Stack Career Guide TECH CAREER & EDUCATION • 2026 Edition • 12 Min Read Is a Coding Degree Obsolete in 2026? How to Land a Full Stack Job with a Portfolio For example, Wondering whether a coding degree is obsolete in 2026? Accordingly, Learn how Full Stack development skills, enterprise-grade projects, GitHub profiles, and a professional portfolio can demonstrate practical software engineering ability. ST Sikdar Technologies Academy Editorial Team Sikdar Technologies Pvt. Ltd. • Learn • Innovate • Succeed i Quick Answer: Is a Coding Degree Obsolete in 2026? For example, No. In reality, a coding or Computer Science degree is not automatically obsolete. However, academic credentials can provide structured foundations, while practical evidence such as technical interviews, coding assessments, projects, internships, GitHub repositories, and professional portfolios can demonstrate applied software development skills. Table of Contents 01 Is a Coding Degree Really Obsolete in 2026? 02 What Employers Look for in a Full Stack Developer 03 Degree vs. Skills vs. Portfolio Comparison 04 Becoming a Full Stack Developer Without a CS Degree 05 What a Full Stack Developer Portfolio Must Include 06 Enterprise-Grade Projects That Stand Out 07 Turning Projects Into Technical Case Studies 08 Building a Professional GitHub Profile 09 Crafting a High-Impact Developer Resume 10 The 90-Day Full Stack Career Action Plan 11 Frequently Asked Questions CAREER REALITY Is a Coding Degree Really Obsolete in 2026? In addition, If you are asking whether a coding degree is obsolete in 2026, the answer depends on the role and hiring process. Above all, A Computer Science or related technology degree can provide structured foundations in programming, algorithms, data structures, databases, and operating systems. In addition, Software engineering is also an applied discipline. In addition, Depending on the employer and role, candidates may be evaluated through technical interviews, coding assessments, internships, GitHub repositories, project discussions, and practical demonstrations. Therefore, the more useful question is not simply “Degree or no degree?” Instead, ask: “Can I demonstrate that I understand software engineering principles and can build functional applications?” + The Modern Developer Profile In practice, a balanced professional profile often combines formal education, programming fundamentals, modern tool execution, practical projects, collaboration experience, and interview readiness. CORE ENGINEERING SKILLS What Employers Look for in a Full Stack Developer In addition, Full Stack Development involves much more than building static web pages and connecting them to basic databases. As a result, developers need to understand how frontend, backend, database, API, security, testing, and deployment layers work together. 01 Programming Fundamentals In particular, developers need variables, control flow, data structures, object-oriented paradigms, asynchronous workflows, and structured debugging. 02 Frontend Engineering For example, developers can build responsive user interfaces with HTML5, CSS3, modern JavaScript, TypeScript, React, and component architecture. 03 Backend Engineering Next, developers can design REST APIs, business logic layers, authentication systems, background processing, and scalable server services. 04 Database Engineering Similarly, developers can manage relational and document databases, data modelling, indexing, transactional integrity, and query optimization. 05 API & Integration In addition, developers can create predictable endpoints, integrate third-party services, validate payloads, and manage error codes. 06 Security Engineering Moreover, developers should implement secure user sessions, password hashing, input sanitization, secrets management, and protections against common web vulnerabilities. 07 Git & Collaboration Meanwhile, teams can use Git branching workflows, pull requests, peer code reviews, and shared repository management. 08 Testing & Reliability Furthermore, developers should write unit tests, test API responses, handle integration workflows, and diagnose performance bottlenecks. 09 Cloud & Deployment Finally, developers can configure hosting environments, use Docker containers, manage CI/CD pipelines, and set up SSL certificates. 10 System Architecture However, system-level work also requires an understanding of service boundaries, caching strategies, background queues, scalability limitations, and failure handling. 11 Communication & Engineering Discipline Equally important, articulating technical design choices, writing clear documentation, and collaborating effectively with cross-functional product and business stakeholders. COMPARISON Degree vs. Skills vs. Portfolio Therefore, In summary, these elements represent distinct components of a professional profile rather than interchangeable credentials. Rather, However, their relative importance depends heavily on the hiring organization and role requirements. Factor Formal Degree Technical Skills Portfolio Primary Role Provides structured academic credentials. Demonstrates core technical capability. Exemplifies applied professional work. Evidence Course transcripts and university projects. Validated via coding tests and live interviews. Showcased through code repositories and live apps. Best Demonstrates Theoretical computer science foundation. Problem-solving and syntax fluency. Real-world implementation capacity. Long-Term Value Enduring academic qualification. Continuously evolving technical competence. Verifiable track record of project delivery. Overall, the strongest professional profile combines solid academic or conceptual fundamentals with verified practical execution. SIKDAR TECHNOLOGIES ACADEMY Build Skills. Build Systems. Build Your Career. As a result, Explore structured technology training focused on practical development, guided projects, and career-oriented learning. Explore Academy → CAREER PATH Can You Become a Full Stack Developer Without a CS Degree? Therefore, Yes. Regardless, For example, today, people enter software engineering from diverse educational and professional backgrounds. Moreover, candidates without a Computer Science degree can develop relevant programming proficiency through structured learning, deliberate practice, and project work. First — Programming Mastery: Build strong logic and problem-solving fundamentals. In addition — Frontend Engineering: Learn modern web layouts and responsive UI design principles. Similarly — Backend Architecture: Construct secure APIs, database connections, and server workflows. Specifically — Data Modeling: Master database design, indexing, and query structures. Finally — Engineering Best Practices: Understand version control, testing protocols, and security standards. Project Execution: Build comprehensive applications that integrate multiple system layers. For example, interview readiness means explaining your architectural choices and implementation code clearly. Moreover, Sikdar Technologies Academy specializes in structured technology learning and practical project-based development. PORTFOLIO What Should a Full Stack Developer Portfolio Include? Similarly, For a strong portfolio, engineering depth should be communicated rather than simply displayed through screenshots. Similarly, More importantly, each featured project should explain the problem, architecture, technical decisions, implementation, testing, and deployment approach. 01 Professional Portfolio Website For example, a responsive landing page presenting your background, core technical stack, and highlighted projects.

google.com, pub-8966458381222183, DIRECT, f08c47fec0942fa0
Business & Digital Strategy, Industry Solutions, Software Development

How to Integrate AI into Legacy Software Without Downtime

Enterprise Modernization & AI How to Integrate AI into Legacy Software Without Operational Downtime A pragmatic executive guide to adopting modern artificial intelligence across established corporate databases, core ERPs, and legacy applications without risky rebuilds. By Sikdar Technologies Pvt. Ltd. • Reading Time: 13 Mins Executive boards and corporate leadership teams face intense pressure to deploy artificial intelligence. Specifically, business leaders want generative search, workflow automation, and predictive analytics embedded directly into daily operations. However, enterprise reality presents a significant technical hurdle. In fact, most established mid-market enterprises run their core daily business on software platforms built a decade ago. These systems, including custom ERPs, legacy financial ledgers, and on-premise relational databases, house an organization’s most critical business intelligence. The Executive Dilemma: Scrapping an operational legacy system to build an AI-native application from scratch is cost-prohibitive and introduces massive business risk. Conversely, doing nothing allows agile competitors to outpace your operational efficiency. Therefore, modern businesses require a middle path. Specifically, organizations can integrate AI into legacy software using decoupled API middleware and secure data integration pipelines. This pragmatic strategy modernizes your core digital infrastructure without interrupting active customer operations. The Safe AI Modernization Pipeline Connecting modern Large Language Models (LLMs) directly to fragile legacy databases creates severe security and stability risks. Instead, companies use a decoupled integration pipeline to preserve database stability: 01 Legacy System & Data Repositories Core Asset ↓ 02 Read-Only Replication & Data Cleaning Isolation Layer ↓ 03 API Middleware & Security Gateway Access Control ↓ 04 Vector Knowledge Base & Semantic Search Context Engine ↓ 05 Secure Enterprise AI Application Layer Business Output 4 Critical Obstacles to Legacy AI Modernization Before writing code, leadership teams must navigate several structural challenges. Specifically, unaddressed legacy constraints can trigger severe data corruption or budget overruns: 01. Siloed, Undocumented Legacy Data Structures The Problem Older corporate software stores valuable data across fragmented, poorly documented tables with contradictory database keys. Business Impact Consequently, AI models produce inaccurate business reports or hallucinated answers because the underlying training context is incomplete. Strategic Solution: Build an intermediate data normalization pipeline. Specifically, clean, validate, and standardize data before exposing records to AI indexing tools. 02. Severe Data Privacy and IP Leakage Risks The Problem Developers often connect consumer AI endpoints directly to internal company databases without data filtering. Business Impact As a result, proprietary corporate secrets and sensitive customer records risk being absorbed into public AI training sets, violating regulatory compliance. Strategic Solution: Deploy private enterprise cloud endpoints with strict data-at-rest encryption. In addition, enforce automated redaction of Personally Identifiable Information (PII). 03. Production Database Performance Bottlenecks The Problem AI data querying requires extensive compute power. Pointing automated queries at live transactional databases causes resource exhaustion. Business Impact Therefore, frontline staff experience application lockups and slow checkout portals during peak business hours. Strategic Solution: Use asynchronous read replicas. In particular, run AI indexing operations against segregated data copies rather than live operational tables. 04. Absence of Modern REST or GraphQL APIs The Problem Many 15-year-old enterprise applications rely on deprecated file exports (such as CSV or SOAP) rather than modern API contracts. Business Impact Thus, development stalls for months while engineers build unexpected custom connectors, inflating project costs. Strategic Solution: Construct an API abstraction middleware layer. Specifically, wrap legacy database triggers with modern microservice adapters. How to Integrate AI into Legacy Software: A 5-Stage Framework To reduce operational exposure, organizations must implement AI modernization incrementally. At Sikdar Technologies Pvt. Ltd., we follow a structured delivery approach that decouples modern AI capabilities from legacy business software: Stage 1: Establish Read-Only Data Ingestion First, create an isolated read-replica of your core operational database. Never permit an experimental AI pipeline to execute direct write queries against your production tables. In addition, establish scheduled data pipelines to export, sanitize, and validate business records into an external storage warehouse. Stage 2: Construct API Translation Middleware Next, build a lightweight API gateway between your legacy software and modern cloud services. This middleware serves as a secure interpreter. Specifically, it translates incoming requests into secure query formats, validates role permissions, and monitors system resource usage. Stage 3: Implement Retrieval-Augmented Generation (RAG) & Agent Workflows Rather than retraining an expensive foundational model, enterprise leaders utilize Retrieval-Augmented Generation (RAG). In plain business terms, RAG acts as an intelligent search engine that references your internal documentation before answering. Consequently, the AI grounds every response in verified company data, minimizing hallucinations. Furthermore, modern enterprise integration extends beyond basic document search to include agentic workflows. By connecting RAG to autonomous software agents, the integration can execute background tasks—such as matching incoming invoices or generating inventory notices—without manual intervention. In addition, for organizations with strict compliance needs, lightweight Small Language Models (SLMs) can be deployed inside your private VPC, eliminating recurring third-party API token expenses. Stage 4: Enforce Role-Based Access Control (RBAC) Furthermore, an executive assistant should not see the same payroll information as the CFO. Therefore, organizations must integrate their existing identity management systems (such as Microsoft Entra ID or Active Directory) directly into the AI middleware. As a result, the model only answers questions using documents the user is authorized to read. Stage 5: Deploy High-Value Internal Pilots First Finally, test your AI integration with internal operational teams before releasing customer-facing tools. For example, deploy an internal operational assistant that helps customer support staff search warranty histories faster. Once validated, expand the integration to external workflows. Rebuilding from Scratch vs. API Middleware Integration When evaluating digital transformation options, leadership teams must balance capital expenditure against operational risk. Consider this architectural comparison: Strategic Factor API Middleware Integration (Recommended) Full Ground-Up Rebuild (Rip & Replace) Operational Disruption Negligible; primary legacy workflows operate normally during integration. High; extensive data migration risks and extended training downtime. Capital Expenditure Moderate; leverages existing infrastructure and proven databases. Substantial; requires funding an entirely new application build. Time-to-Value Rapid; initial internal pilot modules can deploy in iterative phases. Delayed; months or years pass before first production release. Data Integrity Risk Low; isolated read-replicas

google.com, pub-8966458381222183, DIRECT, f08c47fec0942fa0
Business & Digital Strategy, Industry Solutions, Software Development

Why Most Custom Software Projects Fail & How to Prevent It

Custom Software Development Why Do Custom Software Projects Fail? 18 Common Reasons and How to Prevent Them An executive guide to de-risking technology investments, identifying early warning signs, aligning business intent with engineering execution, and choosing the right technology partner. By Sikdar Technologies Pvt. Ltd. • Reading Time: 14 Mins Every year, business owners, enterprise leaders, and startup founders make substantial investments in custom software development. The goals are pragmatic: automate time-consuming manual workflows, replace rigid legacy systems, expand operating margins, or launch a proprietary digital product that provides a sustainable market advantage. Yet across the technology industry, an uncomfortable reality persists: a significant portion of custom software initiatives fail to deliver their anticipated business outcomes. Budgets experience uncontrolled expansion. Delivery dates drift quietly from quarters into years. Codebases slow down under real transactional volume. Most frustrating of all, platforms are finally deployed only to encounter fierce resistance from the frontline employees or customers expected to use them. The Central Reality: Most custom software projects do not fail because developers lack coding skills. They fail because business objectives, functional requirements, upfront planning, cross-team communication, and engineering execution become disconnected. Custom software development is not an isolated coding exercise that can be handed off and forgotten. It is a business transformation initiative enabled by technology. When organizations treat software builds as transactional commodity purchases rather than strategic investments, costly failures become common. Understanding the root causes of failure across both the commercial and technical spectrum is the foundation for safeguarding your capital and your operational sanity. How Software Projects Go Off Track Software project failure rarely happens overnight. It is a compounding sequence of missteps where early gaps in business analysis trigger systemic delivery roadblocks: 01 Unclear Requirements & Business Alignment Root Cause ↓ 02 Uncontrolled Scope Changes Scope Creep ↓ 03 Inadequate Architecture & Planning Design Deficit ↓ 04 Compounding Development Delays Execution Stress ↓ 05 Compromised Quality & Defect Spikes Testing Squeeze ↓ 06 Friction-Heavy User Adoption Rollout Rejection ↓ 07 Depreciated Business Return on Investment (ROI) Project Failure 10 Warning Signs Your Software Project Is Heading Toward Failure Distressed projects provide early operational indicators long before a missed launch date makes the crisis obvious. If your current software initiative exhibits any of the following warning signs, immediate corrective intervention is required: 1. Requirements Shift Without Trade-Off Analysis New features and workflow changes are routinely added to the backlog without formal adjustments to delivery schedules, engineering capacity, or allocated budgets. 2. Absent Product Ownership There is no dedicated internal product owner with the authority to resolve conflicting priorities between departments or define what constitutes a completed feature. 3. No Working Demonstrations Development teams share task lists, slide decks, and wireframes, but cannot demonstrate working, clickable software modules in a staging environment after weeks of work. 4. Coding Commences Before Discovery Engineers begin writing production code before user workflows, database structures, and business logic are clearly documented and approved. 5. Low-Bid Procurement Trap The vendor was selected primarily because they submitted the lowest initial quote, without rigorous technical evaluation of their architectural depth or engineering practices. 6. Absent Quality Assurance Strategy There is no documented test strategy. Testing is treated as an informal task handled by developers checking their own code rather than dedicated QA verification. 7. Security Deferred to Post-Launch Authentication rules, role-based data access permissions, and regulatory compliance standards are treated as items to address after core features are finished. 8. Lack of Direct Repository Access The business does not have administrative ownership of its version control repositories (such as Git), cloud infrastructure accounts, or core architectural documentation. 9. Missing Infrastructure & Support Plans No operational plan exists for data migration, server infrastructure monitoring, routine dependency updates, or post-launch technical support. 10. Measuring Activity Instead of Business Outcomes Project success is tracked exclusively by closed development tickets rather than measurable business metrics such as reduced handling time or error rates. 18 Common Reasons Custom Software Projects Fail Understanding the interplay between business decision-making and technical execution is essential for risk reduction. Here is how software projects break down in practice, alongside actionable preventive guidance. 01. Unclear and Ambiguous Requirements Business Problem The initiative is launched based on high-level operational desires rather than detailed functional specifications. Technical Cause Without concrete acceptance criteria (clear conditions a feature must satisfy), developers build software based on technical assumptions about how business operations work. Business Impact Significant capital and developer hours are spent building features that must be substantially reworked, driving up costs and causing schedule delays. How to Prevent It: Conduct a formal technical discovery phase. Deconstruct operational goals into discrete user stories with clear, testable acceptance criteria before writing production code. 02. Uncontrolled Scope Creep Without Impact Analysis Business Problem Stakeholders continuously introduce “small” feature additions during active development without assessing their cumulative impact on the project. Technical Cause Mid-flight additions alter core database models and break existing integrations, requiring engineers to rewrite previously completed modules. Business Impact Release dates slip repeatedly, budgets are exhausted before the original core system is finished, and team momentum stalls. How to Prevent It: Implement a formal Change Request (CR) protocol. Any feature added to the active scope must explicitly state its impact on delivery dates and budget, or be scheduled for a subsequent phase. 03. Automating Broken Workflows (Building Before Diagnosing) Business Problem Management expects custom software to automatically fix a business workflow that is disorganized or broken on paper. Technical Cause Software encodes internal process contradictions directly into application logic and database rules, creating brittle, complex code. Business Impact The software automates operational inefficiencies rather than eliminating them, resulting in minimal return on investment and user frustration. How to Prevent It: Map and streamline business workflows before starting development. Software should accelerate an already verified, efficient operational process. 04. Unrealistic Timelines and Compressed Budgets Business Problem Deadlines are established based on external corporate events or marketing promises rather than technical work assessments. Technical Cause Engineers are forced to bypass automated tests, hardcode

google.com, pub-8966458381222183, DIRECT, f08c47fec0942fa0
Skills for IT jobs in 2026 for students
Sikdar Technologies Academy

10 IT Skills for Students in 2026 to Get Job-Ready

IT Career Guide · 2026 Skills for IT Jobs in 2026: What Students Should Learn The technology job market is changing quickly. Students need more than a degree or a collection of certificates. They need practical technical skills, problem-solving ability, project experience and a clear understanding of the career direction they want to pursue. This guide explains the most useful skills for IT jobs in 2026 and shows how students can turn classroom learning into practical career preparation. Sikdar Technologies Academy Updated 2026 Career & Skills 15 min read 2026 CAREER FORMULA READY → 01 Choose a Direction Identify the technology field that matches your interests. 02 Build Core Skills Learn the technical foundation required for that path. 03 Build Projects Turn your knowledge into practical work you can demonstrate. 04 Gain Experience Develop professional exposure through practical opportunities. Quick Answer What skills should students learn for IT jobs in 2026? Students preparing for IT jobs in 2026 should build a combination of technical and professional skills. Programming, databases, artificial intelligence, data analytics, cybersecurity, cloud computing, DevOps, ERP and communication can support different technology career paths. The practical approach Do not try to learn every technology at the same time. Choose one career direction, learn its core skills, build practical projects and then add supporting technologies. Who This Guide Is For Planning your IT career while you are still a student? The earlier you understand your options, the easier it becomes to choose useful skills and avoid spending months learning technologies that do not match your career goals. 01 · ENGINEERING Computer Science Students Build practical skills alongside your academic subjects and start developing projects before graduation. 02 · COLLEGE Students Exploring IT Compare technology paths and identify the type of technical work that interests you most. 03 · FRESHERS Recent Graduates Strengthen your technical profile with projects, practical skills and relevant experience. 01 · Core IT Skills The technical foundation students should build first. Technology changes rapidly, but strong fundamentals remain useful. Students should understand programming logic, data, software tools and problem-solving before moving into advanced specialisations. 01 Programming Learn one programming language properly. Focus on variables, functions, logic, data structures, debugging and clean code. 02 SQL & Databases Understand tables, relationships, queries, joins and how applications store and retrieve information. 03 Git & Version Control Learn repositories, commits, branches and collaborative development so your projects follow a professional workflow. 04 Problem Solving Practice breaking large problems into smaller steps and developing solutions instead of depending entirely on tutorials. 05 AI Literacy Understand how modern AI tools can support development, research and productivity while maintaining responsible usage. 06 Communication Learn to explain technical concepts, projects and decisions clearly during interviews, presentations and professional discussions. 02 · Career Paths Popular IT career directions students can explore in 2026. There is no single route into the technology industry. Your best choice depends on the type of problems you enjoy solving and the skills you are willing to develop consistently. 01 Software Development Software development is suitable for students who enjoy programming and building applications. Start with programming fundamentals, databases, version control and APIs before specialising in a development stack. Programming Web Development APIs Git SQL 02 Artificial Intelligence & Machine Learning AI and machine learning combine programming, data and analytical thinking. Students should develop programming and data fundamentals before moving into advanced machine learning concepts. Python Data Machine Learning AI Tools 03 Data Analytics Data analytics focuses on turning information into useful insights. Students can begin with spreadsheets, SQL, statistics and data visualisation before exploring advanced analytics. SQL Statistics Analytics Visualisation 04 Cybersecurity Cybersecurity requires an understanding of networks, operating systems and security principles. Students should build a strong technical foundation before exploring specialised security areas. Networking Linux Security Systems 05 Cloud & DevOps Cloud and DevOps involve infrastructure, deployment, automation and reliable software delivery. Linux, networking and version control are useful starting points. Linux Cloud Docker Automation 06 ERP & Enterprise Technology ERP connects technology with real business processes such as finance, sales, supply chain, manufacturing and human resources. This path can suit students interested in both technology and business operations. ERP SAP Odoo Business Processes 03 · Learning Strategy A better way to learn technology skills. Completing courses is only one part of career preparation. A stronger learning process connects knowledge with application. STEP 01 Learn Understand the concept and learn why the technology is used. STEP 02 Practice Solve exercises and small problems without copying every solution. STEP 03 Build Use your knowledge to create a practical project. STEP 04 Explain Learn to explain your project, decisions and results clearly. 04 · Career Preparation Skills vs certificates: what should students focus on? Certificates can demonstrate structured learning. Practical skills demonstrate what you can actually do. A strong student profile can combine both with projects and relevant experience. Certificates Can Show Completion of a structured program Exposure to a specific subject Commitment to learning Understanding of a defined curriculum Practical Work Can Show Ability to apply concepts Problem-solving ability Project development experience Ability to explain technical decisions 05 · Project Portfolio Build projects that prove you can apply your skills. A project does not need to be enormous. It should solve a clear problem and demonstrate how you use technology to create a working solution. BEGINNER PROJECT Student Management System Create an application that manages student information and demonstrates database and application development concepts. CRUD operations Database integration Search and filtering Form validation DATA PROJECT Business Analytics Dashboard Turn a dataset into a useful dashboard that communicates trends and business information. Data cleaning SQL queries Visualisation Business insights AI PROJECT AI-Powered Application Build a practical application that uses an AI capability to solve a clearly defined user problem. AI integration Application logic Prompt design User experience ENTERPRISE PROJECT ERP Business Workflow Demonstrate how technology can support a real business process through an enterprise workflow. Business process mapping ERP workflow Data management Reporting 06 · Practical Experience Why practical

google.com, pub-8966458381222183, DIRECT, f08c47fec0942fa0
Sikdar Technologies Academy

Skills for IT Jobs in 2026: What Students Should Learn

IT Career Guide · 2026 Skills for IT Jobs in 2026: What Students Should Learn The skills for IT jobs in 2026 are changing as companies adopt artificial intelligence, cloud platforms, cybersecurity tools, data systems and business software. A computer science degree still provides a strong foundation, but students also need practical skills that they can demonstrate through projects, internships and real-world problem solving. This guide explains what students should learn, which technical skills matter most, how to choose a career direction and how to build a practical learning plan without trying to learn every technology at once. By Sikdar Technologies Academy • Updated August 2026 • Career & Skills Start Here What skills do students need for IT jobs in 2026? Technology careers are no longer limited to traditional software development. Companies now hire people for artificial intelligence, data, cloud computing, cybersecurity, enterprise applications, DevOps and many other technology functions. Therefore, choosing a career direction early can make learning more focused. Instead of collecting certificates without practice, students can build a combination of technical knowledge, projects, communication ability and problem-solving skills. The most useful approach is simple: understand the role first, identify the required skills, learn the fundamentals and then prove those skills through practical work. Important: You do not need to master every technology in the IT industry. A focused skill set with strong fundamentals is usually more useful than a long list of unrelated tools. Career Paths Six technology career directions students can explore Each career path has different technical requirements. However, programming fundamentals, logical thinking, communication and practical experience remain useful across almost every direction. 01 / ARTIFICIAL INTELLIGENCE AI & Machine Learning Artificial intelligence is becoming part of software, business operations and digital products. Students interested in this field should begin with Python, mathematics, statistics, data handling and machine learning concepts. 02 / SOFTWARE Software Development Software development remains one of the broadest technology career paths. Students should understand programming, databases, APIs, version control, testing and software development practices. 03 / DATA Data Science & Analytics Data roles combine statistics, programming and business thinking. SQL, Python, data visualisation and analytical reasoning are valuable starting points for this direction. 04 / SECURITY Cybersecurity Security professionals help organisations protect systems, networks, applications and information. Networking, operating systems, security principles and practical labs create a strong foundation. 05 / CLOUD Cloud & DevOps Modern applications depend heavily on cloud infrastructure. Students can learn Linux, networking, containers, cloud concepts, automation and deployment workflows. 06 / ENTERPRISE ERP & Business Technology Enterprise technology connects software with finance, supply chain, sales, operations and other business processes. ERP knowledge can be useful for students who enjoy both technology and business workflows. Core Foundation 10 essential skills for IT jobs in 2026 Before choosing a specialised technology, students should develop a strong technical foundation. These skills support multiple IT career paths and make it easier to learn new tools later. Programming fundamentals — Learn variables, conditions, loops, functions, data structures and basic problem solving. SQL and databases — Understand how applications store, retrieve and manage information. Git and version control — Learn how developers manage code, collaborate and track changes. APIs and web fundamentals — Understand how modern applications communicate with services. Linux basics — Learn commands, files, permissions, processes and basic server concepts. Cloud fundamentals — Understand computing, storage, networking and deployment in cloud environments. Cybersecurity awareness — Learn authentication, access control, common vulnerabilities and secure practices. Data analysis — Develop the ability to clean, understand and communicate information from datasets. AI literacy — Understand how AI tools work at a practical level and learn how to use them responsibly. Communication — Explain technical ideas clearly to teammates, clients and non-technical stakeholders. Technical Skills Which programming skills should students learn? Programming is still one of the most useful foundations for an IT career. However, students should avoid learning several languages at the same time without understanding the basics. A better strategy is to select one primary language and use it to build small applications. Python can be useful for AI, automation, data and general programming. JavaScript is important for web development. Java and other languages are also relevant in many enterprise and application development environments. Focus on concepts before tools Regardless of the language, learn variables, functions, conditions, loops, data structures, error handling and object-oriented concepts. After that, practise by building projects rather than watching tutorials continuously. For example, a beginner can create a student management system, expense tracker or simple business application. Such projects make programming concepts easier to remember because every feature solves a practical problem. AI Skills AI skills every technology student should understand Artificial intelligence is influencing how software is developed, analysed and used. As a result, AI literacy is becoming useful even for students who do not plan to become machine learning engineers. Start with practical AI knowledge Students can begin by understanding machine learning basics, datasets, model training, evaluation and responsible AI use. Python provides a practical entry point for many AI and data workflows. In addition, students should learn how to work with AI-assisted development tools. The important goal is not simply generating code. Instead, students should understand the code, test the result and identify mistakes. Career tip: AI should strengthen your existing technical skills. It should not replace the need to understand programming, databases, security or software fundamentals. Specialisation Cloud, cybersecurity and data skills Beyond programming, several technology areas deserve attention. Cloud platforms support modern applications, cybersecurity protects digital systems and data skills help organisations make better decisions. Cloud computing Begin with servers, networking, storage and deployment concepts. Then move into containers, cloud services and automation. Hands-on practice is especially useful because cloud concepts become clearer when students deploy something themselves. Cybersecurity Networking and operating systems are strong starting points for cybersecurity. Students should also understand authentication, permissions, encryption, common vulnerabilities and secure coding. Ethical practice is essential throughout security learning. Data and analytics SQL is one of the most practical data skills.

Powering Ideas, Shaping Futures

contact@sikdartechnologies.com

project@sikdartechnologies.com

© 2021-2026 Sikdar Technologies Pvt Ltd